How a Dormant Bug Broke Microsoft 365 for 24 Hours
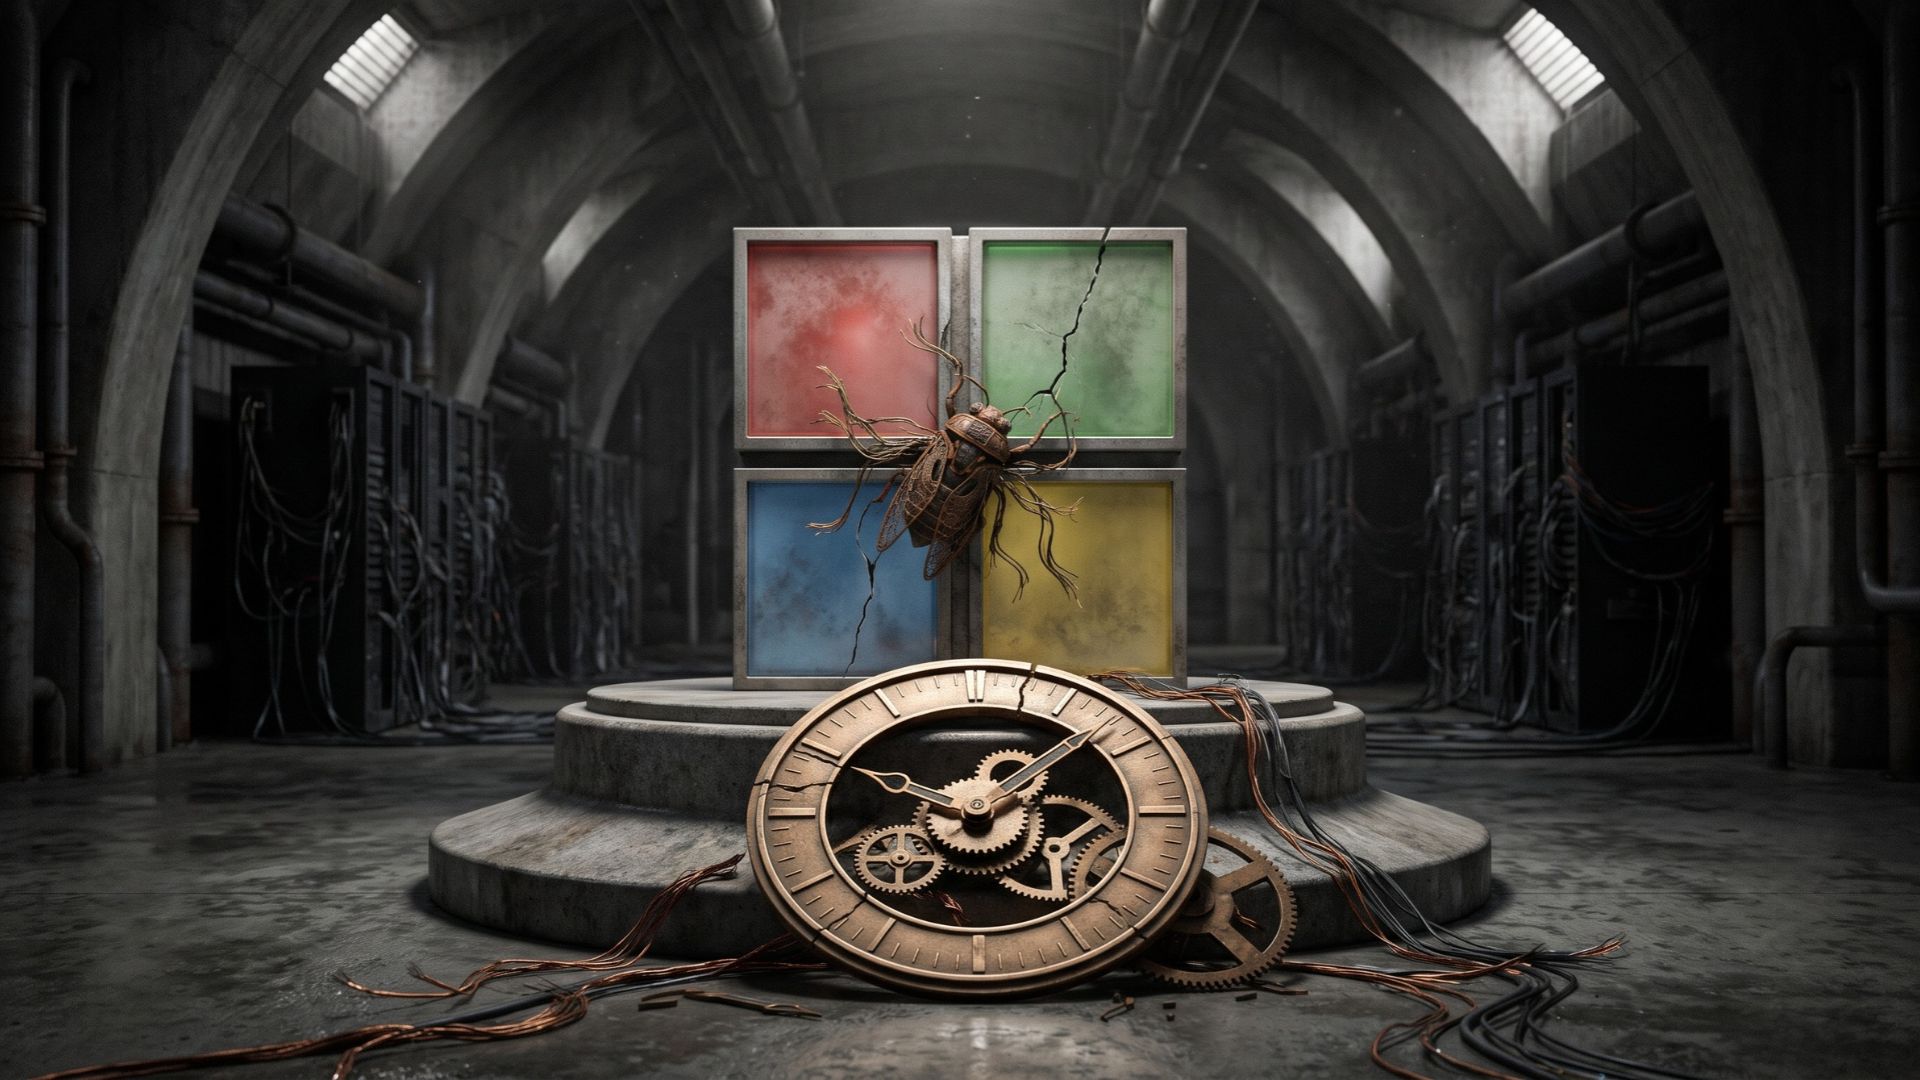
A July gateway update that lay dormant for three months caused a nearly 24-hour Microsoft 365 outage after automated recovery systems spread the failure worldwide.
Listen to this article
5 chapters
In this article
A silent software flaw hiding inside Microsoft’s cloud infrastructure for more than three months triggered a nearly 24-hour global outage that cut businesses off from email and productivity tools. According to a preliminary post-incident report sent to customers, the disruption began on the evening of Thursday, 12 November, and was compounded when Microsoft’s automated recovery systems spread the failure worldwide.
Exchange Online, the backbone behind Outlook, suffered the most severe disruption, leaving millions unable to access mailboxes or send timely messages. In South Africa, major public institutions, including the South African Revenue Service and the City of Cape Town, issued warnings to users as internal communications and public-facing services stalled.
A Hidden Flaw in the Gateway
The root cause traces back to a routine software update Microsoft rolled out in July for a critical networking gateway. This gateway acts as the front door for Microsoft 365, receiving incoming user connections and routing them to services like Exchange. Under heavy traffic conditions, the July update caused internal Windows processes on those gateway servers to lock up while waiting on one another, rapidly exhausting processing power and memory until the machines stopped responding entirely.
For over three months, the code ran globally without incident. Microsoft’s pre-release load testing failed to catch the defect because it primarily affected newer, high-performance servers equipped with higher processor core counts, whereas internal tests relied on older hardware with fewer cores.
When Safety Nets Become the Problem
The dormant bug finally awakened after a routine operational shift. Early on Thursday, automated traffic systems moved Microsoft Teams traffic from a separate gateway onto the primary gateway handling Exchange Online. At the time, nearly 14% of that gateway’s server capacity was already offline due to an unrelated issue the day before.
When peak North American user traffic hit the reduced-capacity gateway, servers began crashing. Instead of containing the damage, Microsoft’s automated traffic management system routed incoming users away from unresponsive servers and onto healthy ones. That sudden surge pushed the remaining machines past their breaking point, sparking a domino effect. Within two hours, more than 80% of the gateway’s servers were unresponsive, while regional isolation barriers meant to stop failures from crossing borders failed due to a separate, still-unexplained issue.
Why Email Took Longest to Recover
Restoring service proved unusually difficult because engineers could not rely on standard rapid-rollback tools to undo a code change that had been live for over three months. Every time technicians rebooted a server, a massive backlog of waiting user traffic immediately swamped the machine and crashed it again.
After 15 hours of troubleshooting, engineers began manually pulling server groups offline, applying a patch to revert the July update, and restarting them region by region in line with global business hours. While apps like Teams, OneDrive, and SharePoint recovered earlier by shifting traffic to alternative gateways, Exchange Online could not be rerouted due to its immense scale, leaving webmail disrupted for roughly 22 hours.
Claims and Lessons in Cloud Centralization
In response to the incident, Microsoft has implemented stricter limits on automated traffic redistribution, added new monitoring safeguards, and extended email queuing windows so delayed messages deliver rather than bounce back. Affected enterprise customers whose webmail remained unavailable throughout the outage may qualify for a 50% service credit on their monthly fees under Microsoft’s service level agreement, though administrators must manually file claims by 31 December, and credits do not cover broader business losses.
For organizations reliant on single-vendor cloud ecosystems, the incident serves as a stark reminder of how fragile centralized infrastructure can be when automated failover mechanisms turn localized bugs into global single points of failure. Microsoft is scheduled to release its final, comprehensive report on the outage on 20 November.
The Morning Brief
Start every day knowing what matters in tech
Six stories chosen by our editors, in your inbox at 06:00 UTC. Free.
Instant notifications in this browser when big news breaks. No email needed, and you can turn them off any time.
See more Blockrora in Google
Make us a preferred source and our stories show up more often in Top Stories.
Editor and Writer at Blockrora. Backed by years in mainstream tech and health tech development, Lauren covers digital health, tech adoption, and the societal shifts shaping the web. Wellness advocate and coastal wanderer.
More from Lauren →